

TL;DR
- It has never been easier to affect AI visibility. Unlike traditional rankings, we can see the information needs AI is working from, trace them, and change what AI says.
- Diagnose before you optimize. Garrett’s six-check flowchart moves from eligibility (ranked, retrieved) to presence (cited, mentioned) to preference (recommended, framed correctly). It is a diagnostic tool, not a causal funnel.
- Recommendation rate is the number that matters. Being visible isn’t enough. The question is how often AI answers to a buying-decision prompt actually recommend you, compared with competitors.
- Most of what drives AI visibility is controlled by other departments. Legal owns your website claims, PR owns publisher relationships, and brand owns the open web. Getting approval is the hard part.
- Stop pitching traffic. Pitch each department its own outcome. Sales wants shortlist presence, legal wants control of the claims AI repeats, and the CFO wants to know what the spend will deliver and when.
About the Speaker
Garrett French is the Founder and CEO of Citation Labs, ZipSprout, and Xofu. He has worked in search since 2001 and founded Citation Labs in 2011 as a link-building agency. He noted, with some amusement, that naming the company “Citation Labs” 15 years ago turned out to be well-timed now that citations have become central to AI search.
A note on the session content: the published abstract describes a buying-committee teardown comparing the pages AI cites for different roles in one purchase decision. The talk delivered on the day focused instead on diagnosing AI visibility gaps and building internal buy-in. This report covers what was presented.
The Problem: A Link Builder in a World Without Traffic
Garrett was candid about where his own business stands. From 2024, organic traffic started declining for many clients. For an agency built on links, that brought more scrutiny and harder conversations about why clients should keep investing. His summary of the current climate: steady is the new growing.
The question he kept hearing over the last two years was some version of: why keep spending on this if it doesn’t bring traffic?
His good news: right now is the easiest it has ever been to influence AI visibility. With traditional search, you could never see exactly what information the algorithm needed. With AI, you can. Query fan-outs expose the questions AI asks itself while solving a user’s problem. Those information needs are explicit, at least for now, and that means they can be traced and addressed.
The Solution, Part 1: Diagnose the Gap
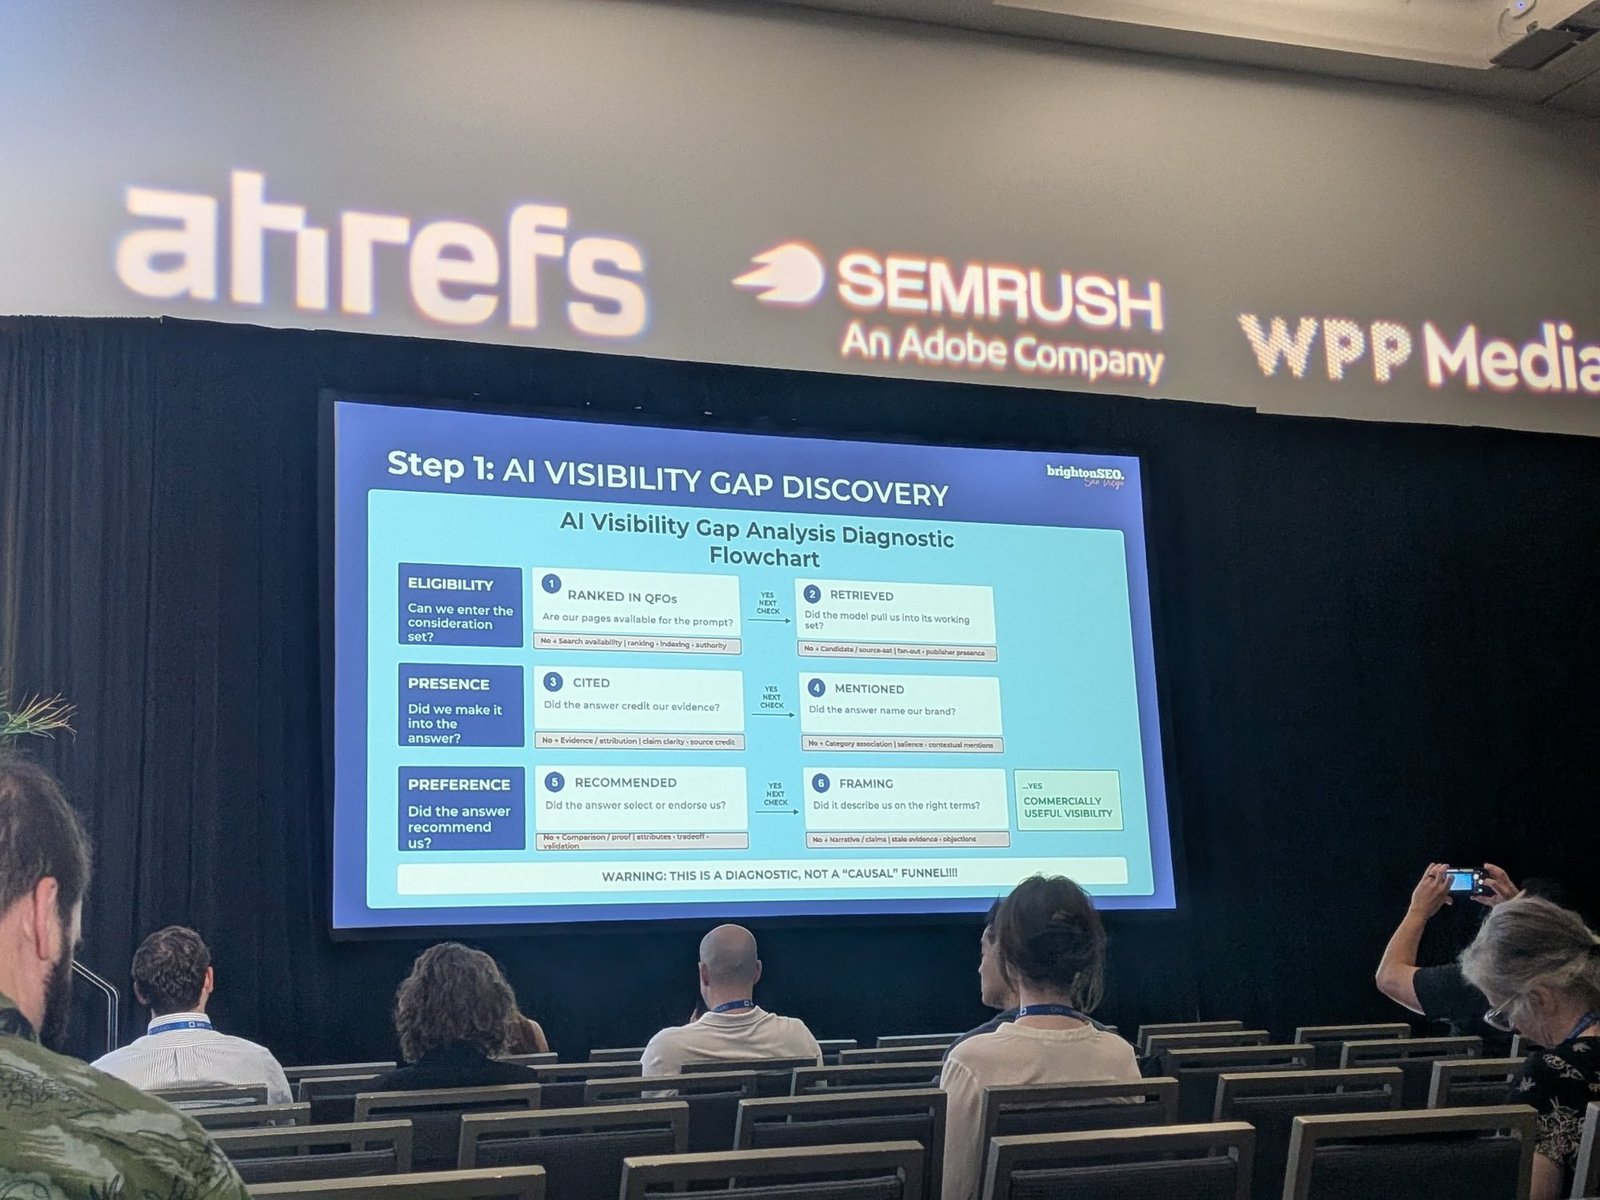
The foundation of Garrett’s approach is a six-step diagnostic flowchart organized into three layers. At each step, if the answer is no, the flowchart tells you where to investigate.
Eligibility: can we enter the consideration set?
- Ranked in query fan-outs. Are our pages available for the prompt? If not, look at search availability, ranking, indexing, and authority.
- Retrieved. Did the model pull us into its working set? If not, look at the candidate source set, fan-out coverage, and publisher presence.
Presence: did we make it into the answer?
- Cited. Did the answer credit our evidence? If not, look at evidence and attribution, claim clarity, and source credit.
- Mentioned. Did the answer name our brand? If not, look at category association, salience, and contextual mentions.
Preference: did the answer recommend us?
- Recommended. Did the answer select or endorse us? If not, look at comparisons, proof, attributes, trade-offs, and validation.
- Framing. Did it describe us on the right terms? If not, look at narrative and claims, stale evidence, and unaddressed objections.
If all six checks pass, the result is what Garrett calls commercially useful visibility.
The slide carried a clear warning: this is a diagnostic, not a causal funnel. Passing one step doesn’t cause the next. It is a structured way of deciding where to start your investigation.
The Solution, Part 2: Start From the Decision, Not the Keyword
Garrett’s example prompt was built around a purchasing decision in industrial computing. No brand appears in the prompt. We don’t know whether real customers type this exact wording, but the decision it represents is one an actual buyer would face.
That is the shift in the title. Keywords map to search results. Decisions map to the final choice point, where a buyer asks what they need to know before selecting a vendor. The AI’s fan-out queries at that moment reveal the information needs you should be meeting.
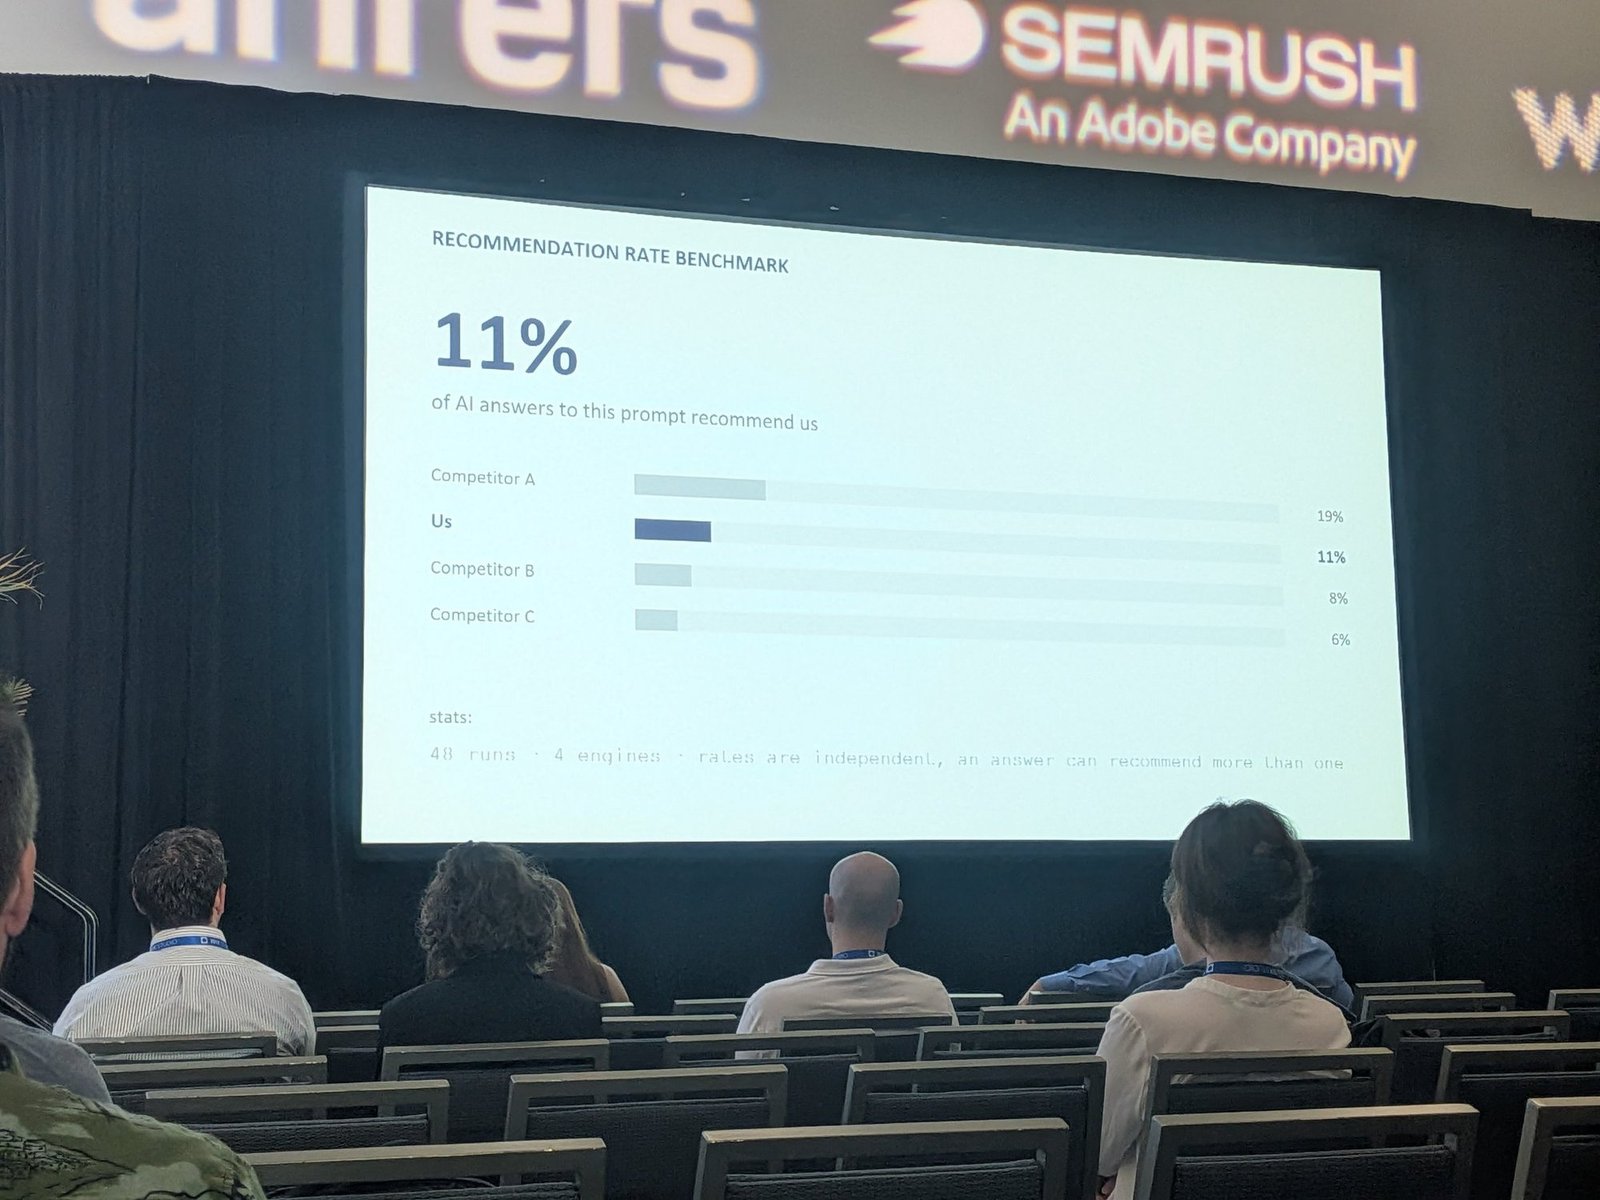
From there, Garrett measures recommendation rate: the share of AI answers to a decision prompt that recommend you. In his sample benchmark, based on 48 runs across four AI engines:
- Competitor A: 19%
- Us: 11%
- Competitor B: 8%
- Competitor C: 6%
Rates are independent, since one answer can recommend more than one company.
He described arriving at this metric as a slow, painful, iterative process over two years. Once you track it over time, you can publish an intervention and show whether the recommendation rate moved.
The interventions don’t have to be on your own site. You can work with PR, or approach the pages AI already cites frequently for your target decisions and ask them to update what they say about you.
The Hard Part: Getting Approval
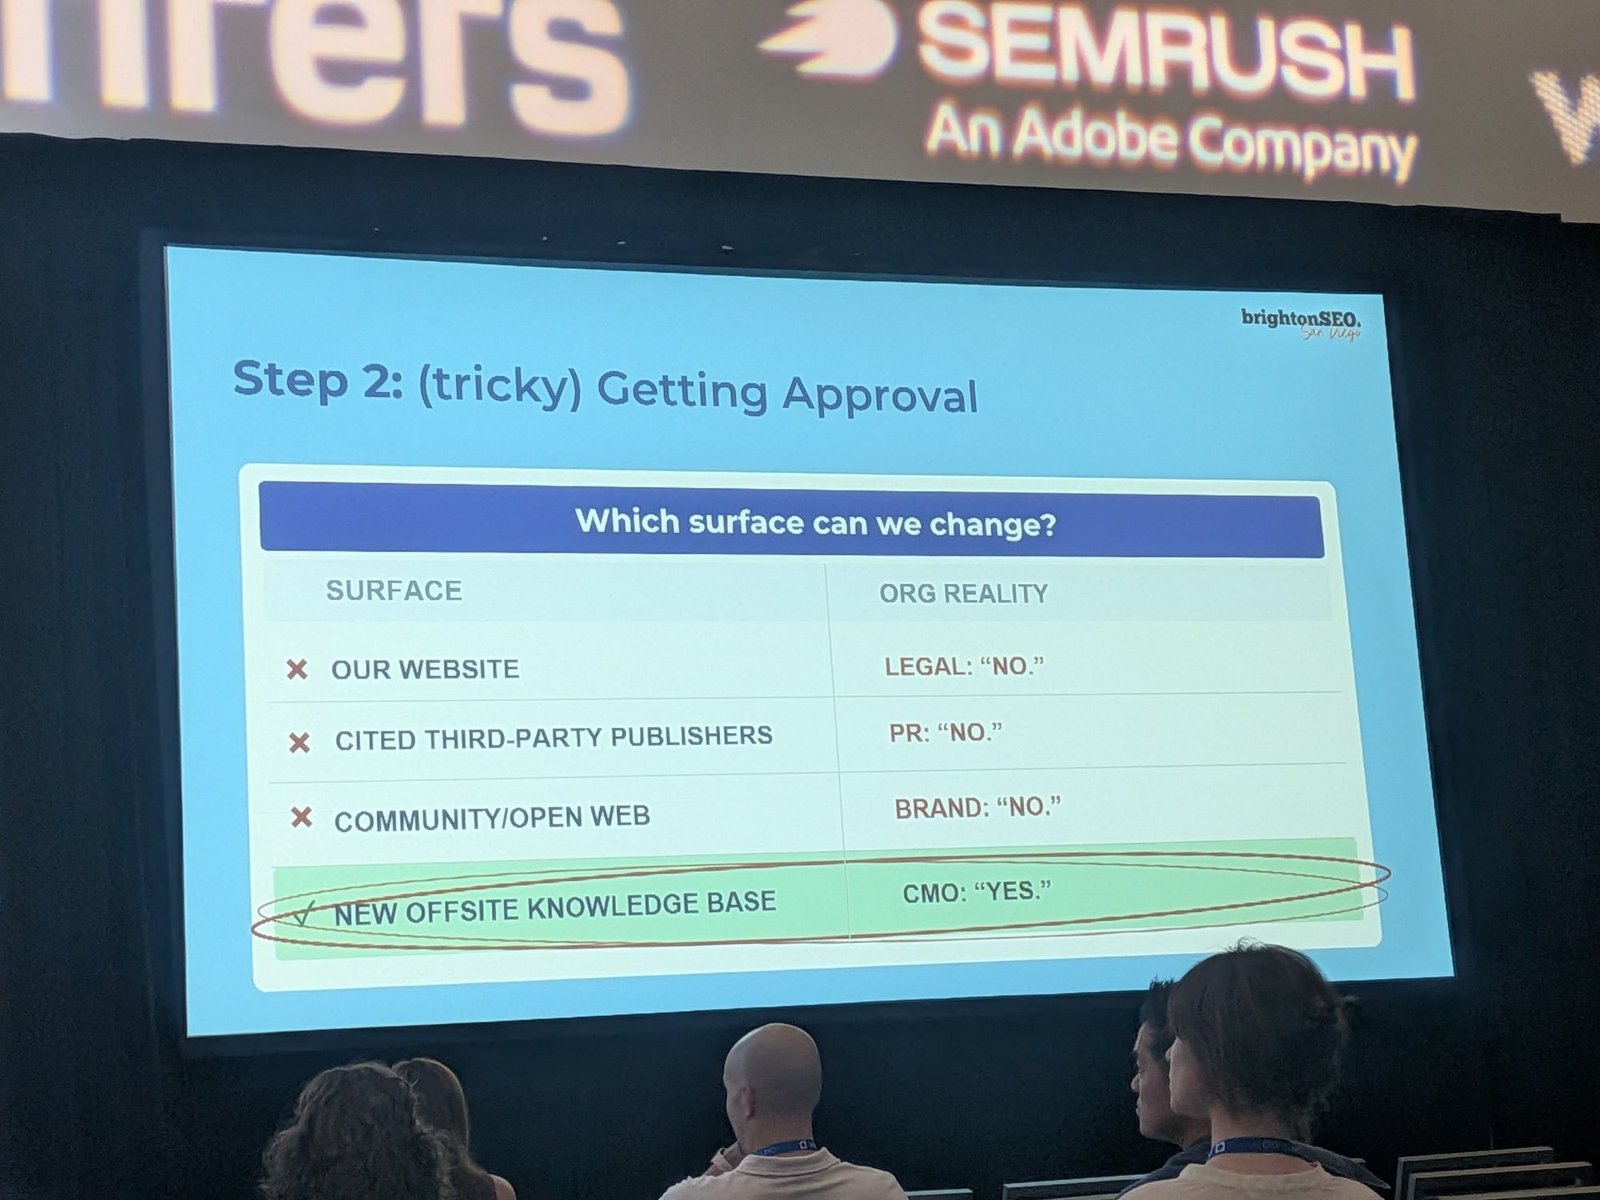
This was the most relatable slide of the session. Garrett acted out a scenario of an urgent meeting with the CEO, sales, PR, and legal in the room, then showed the organizational reality of trying to change any surface that influences AI:
| Surface | Organizational reality |
|---|---|
| Our website | Legal: “No.” |
| Cited third-party publishers | PR: “No.” |
| Community / open web | Brand: “No.” |
| New offsite knowledge base | CMO: “Yes.” |
In his example, the only surface that got approved was a new offsite knowledge base. Everything else AI was drawing from belonged to someone else.
His conclusion is one every search team needs to hear: so much of what affects AI visibility is controlled by other people in the organization. That means search professionals need to talk to sales, PR, and legal far more than before. Previously, traffic justified itself and there was no need to enter those conversations. That era is over.
The Blueprint: Same Work, Different Outcomes
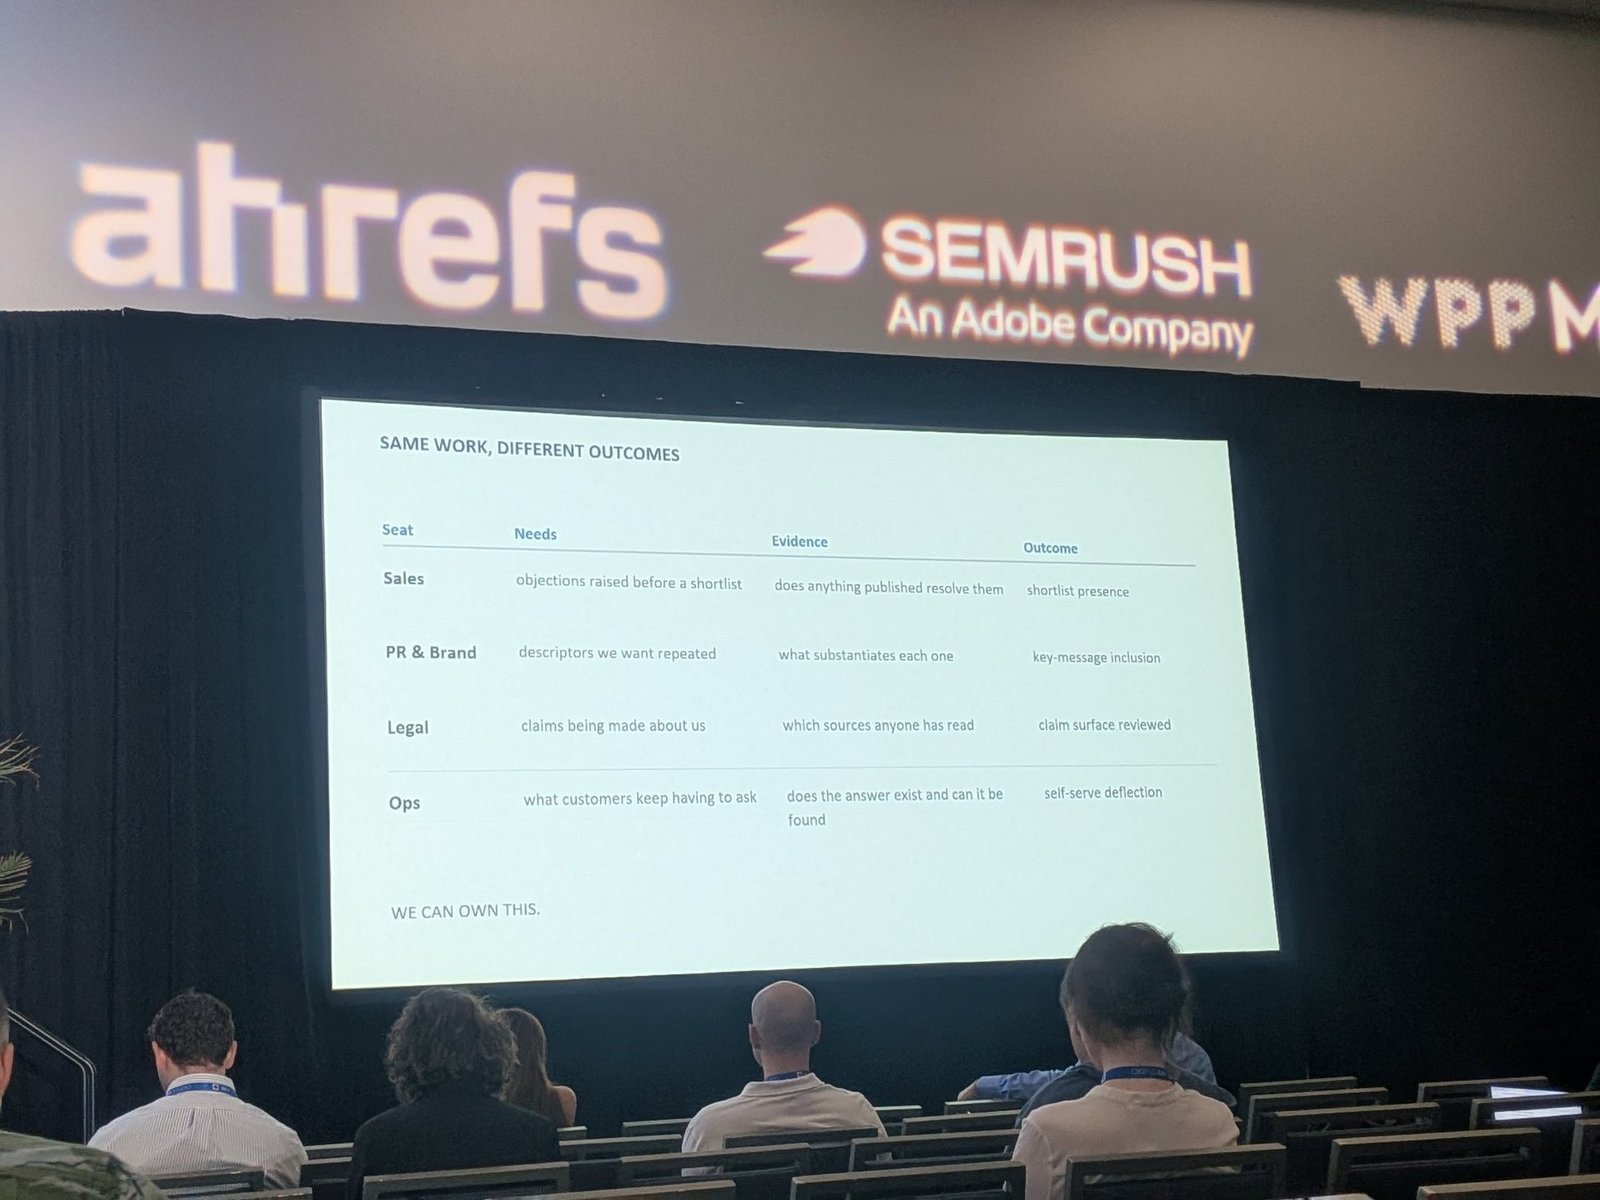
The practical core of the talk was reframing the same AI visibility work as a different outcome for each department:
| Team | What they need | Evidence to check | Outcome |
|---|---|---|---|
| Sales | Objections raised before a shortlist | Does anything published resolve them? | Shortlist presence |
| PR & Brand | Descriptors we want repeated | What substantiates each one? | Key-message inclusion |
| Legal | Claims being made about us | Which sources has anyone read? | Claim surface reviewed |
| Ops | What customers keep having to ask | Does the answer exist, and can it be found? | Self-serve deflection |
The slide’s closing line was short: we can own this.
Garrett then showed sample pitches for each audience. The figures in these slides are illustrative baseline-to-target models, not client results.
The Sales Pitch
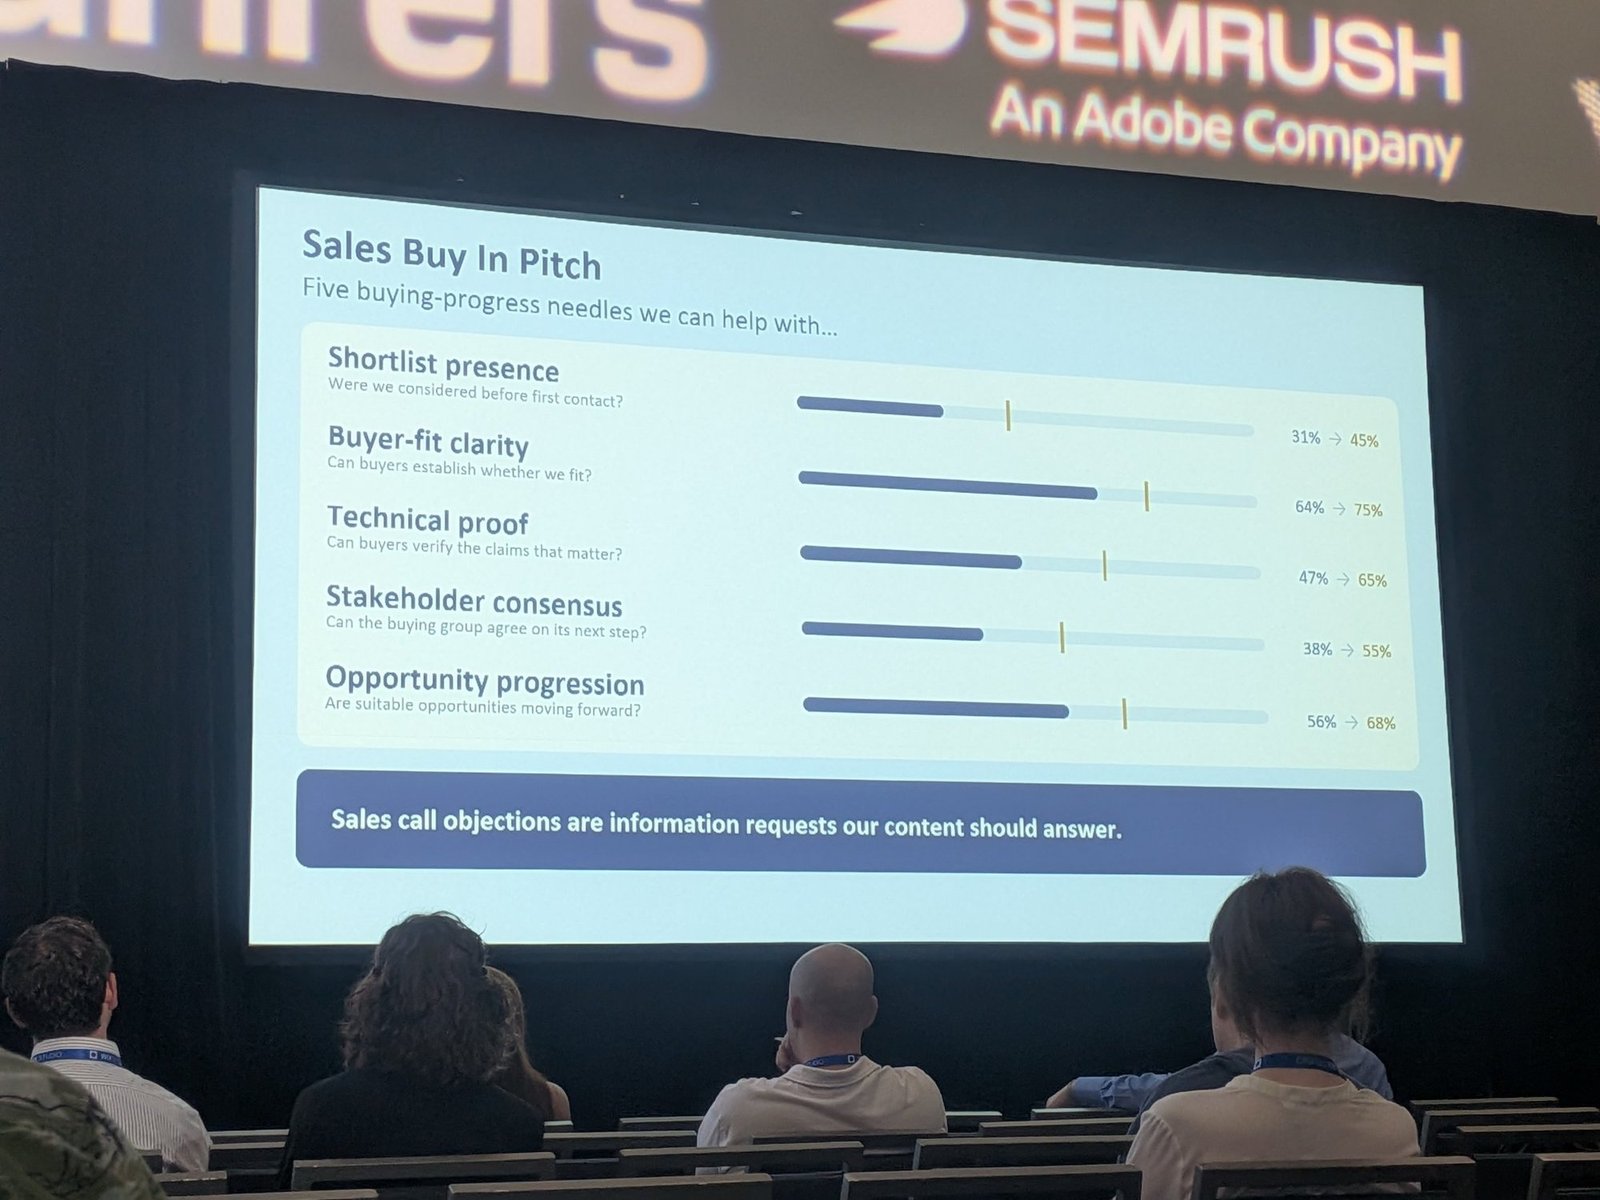
Five buying-progress measures content can help with:
- Shortlist presence: were we considered before first contact? (31% to 45%)
- Buyer-fit clarity: can buyers establish whether we fit? (64% to 75%)
- Technical proof: can buyers verify the claims that matter? (47% to 65%)
- Stakeholder consensus: can the buying group agree on its next step? (38% to 55%)
- Opportunity progression: are suitable opportunities moving forward? (56% to 68%)
The message to sales: objections on sales calls are information requests our content should answer.
The PR and Brand Pitch
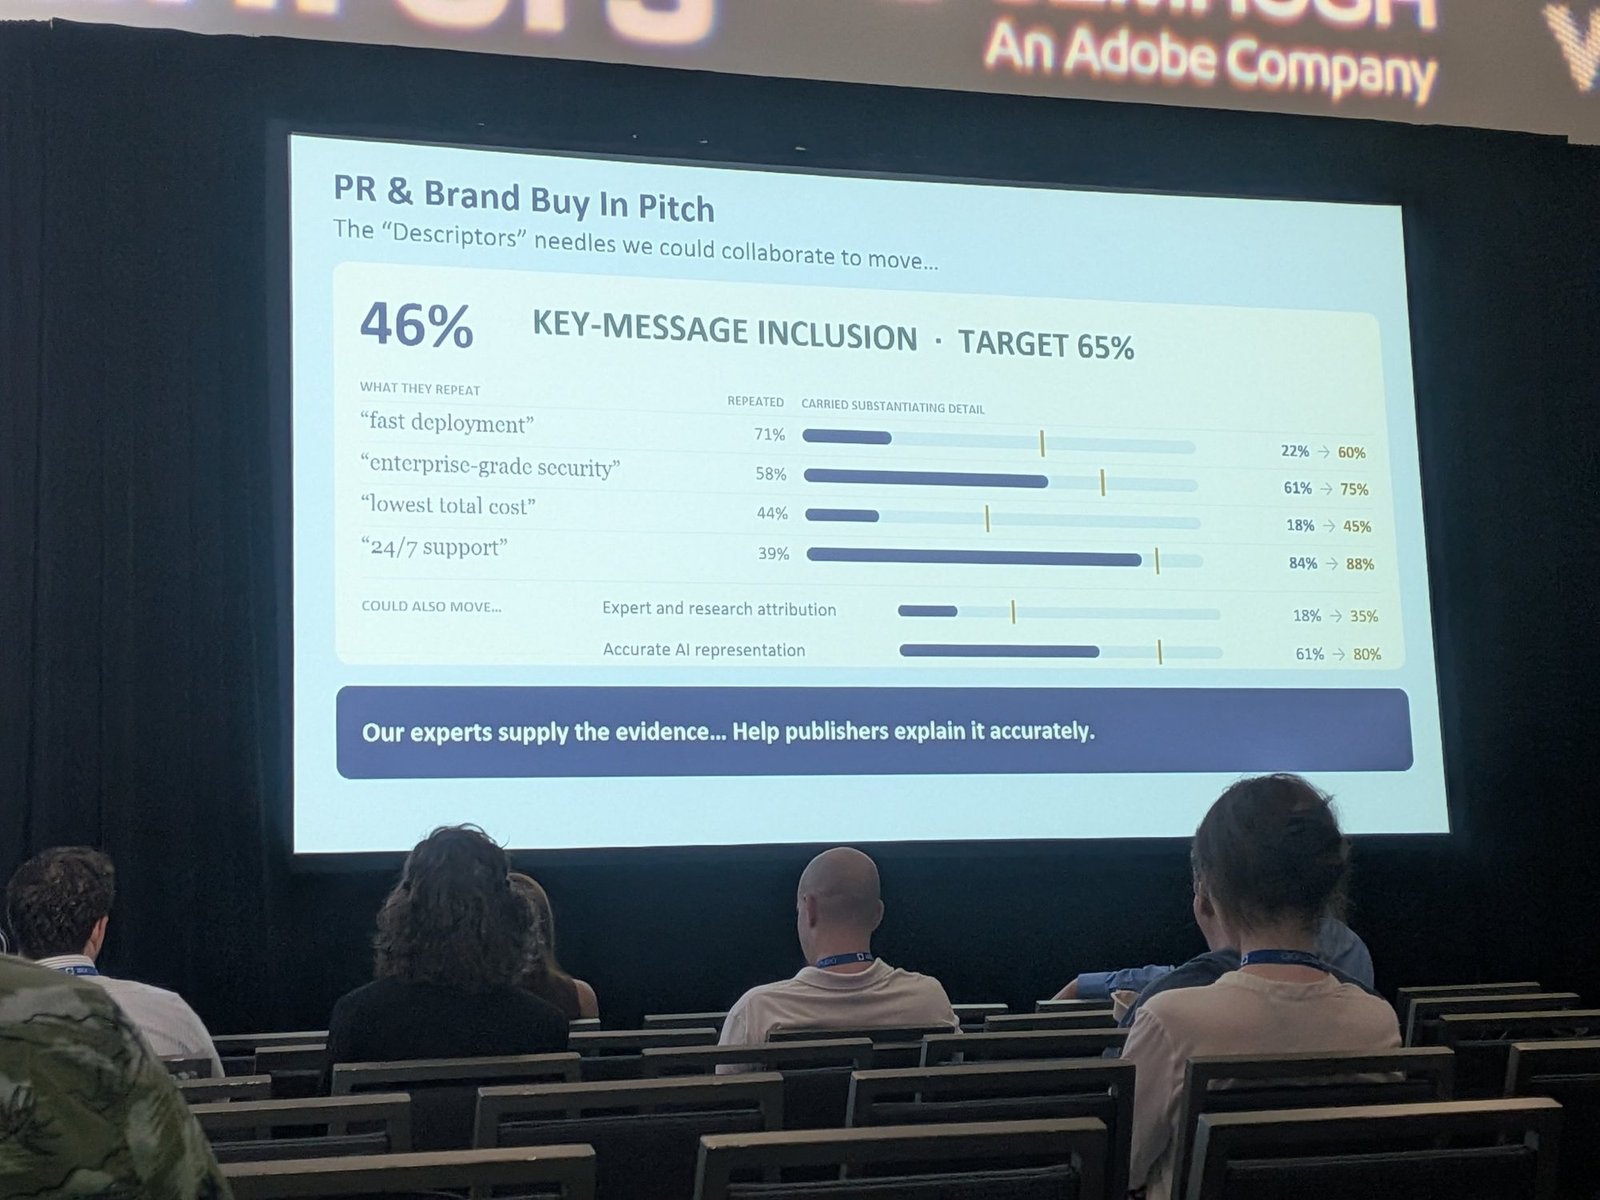
The PR and brand pitch starts from the descriptors the company wants repeated, and asks how often publishers repeat them and how often they carry the detail that substantiates them. In the example, key-message inclusion sits at 46% against a target of 65%:
- “fast deployment”: repeated 71% of the time, substantiating detail 22% to 60%
- “enterprise-grade security”: repeated 58%, detail 61% to 75%
- “lowest total cost”: repeated 44%, detail 18% to 45%
- “24/7 support”: repeated 39%, detail 84% to 88%
Two further measures could also move: expert and research attribution (18% to 35%) and accurate AI representation (61% to 80%).
The line on this slide: our experts supply the evidence, so help publishers explain it accurately.
The Legal Pitch
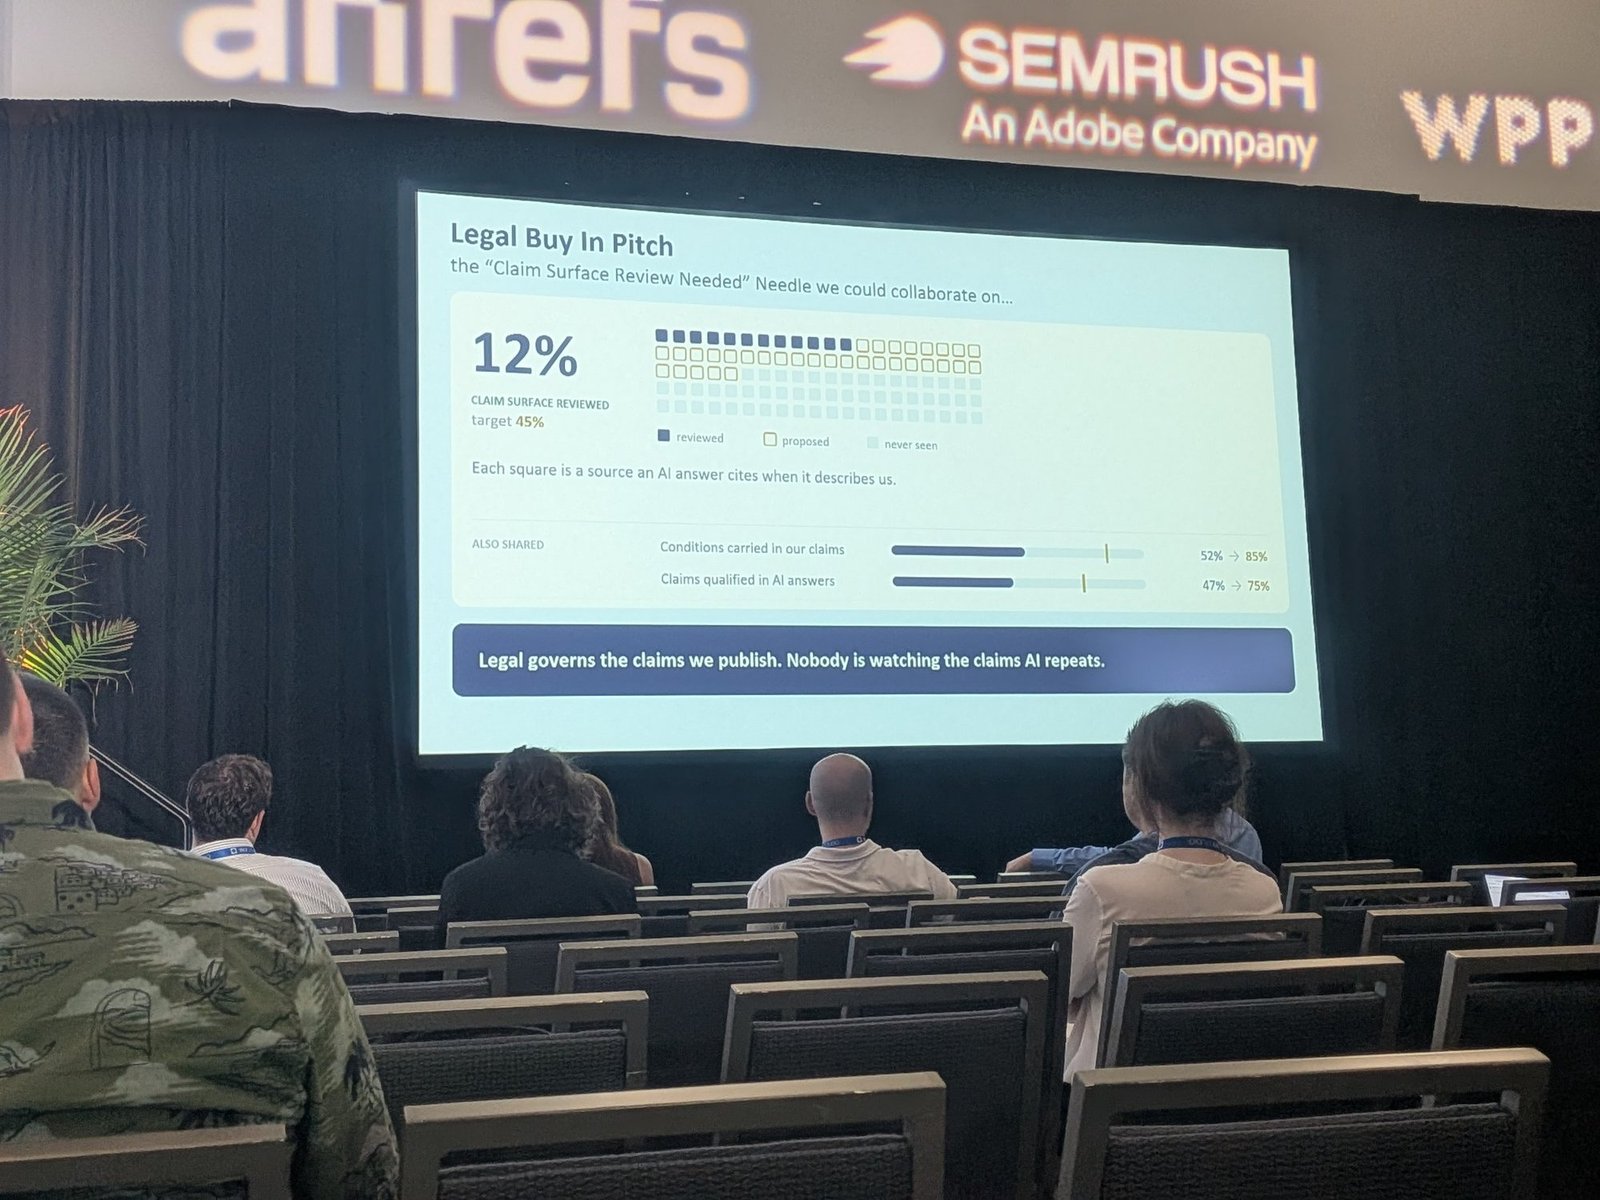
The legal pitch visualizes every source an AI answer cites when it describes the company. In the example, only 12% of that claim surface has been reviewed, against a target of 45%. Two shared measures sit alongside it: conditions carried in our claims (52% to 85%) and claims correctly qualified in AI answers (47% to 75%).
The line on this slide is the strongest argument I heard all day for involving legal: legal governs the claims we publish, but nobody is watching the claims AI repeats.
The CFO Pitch
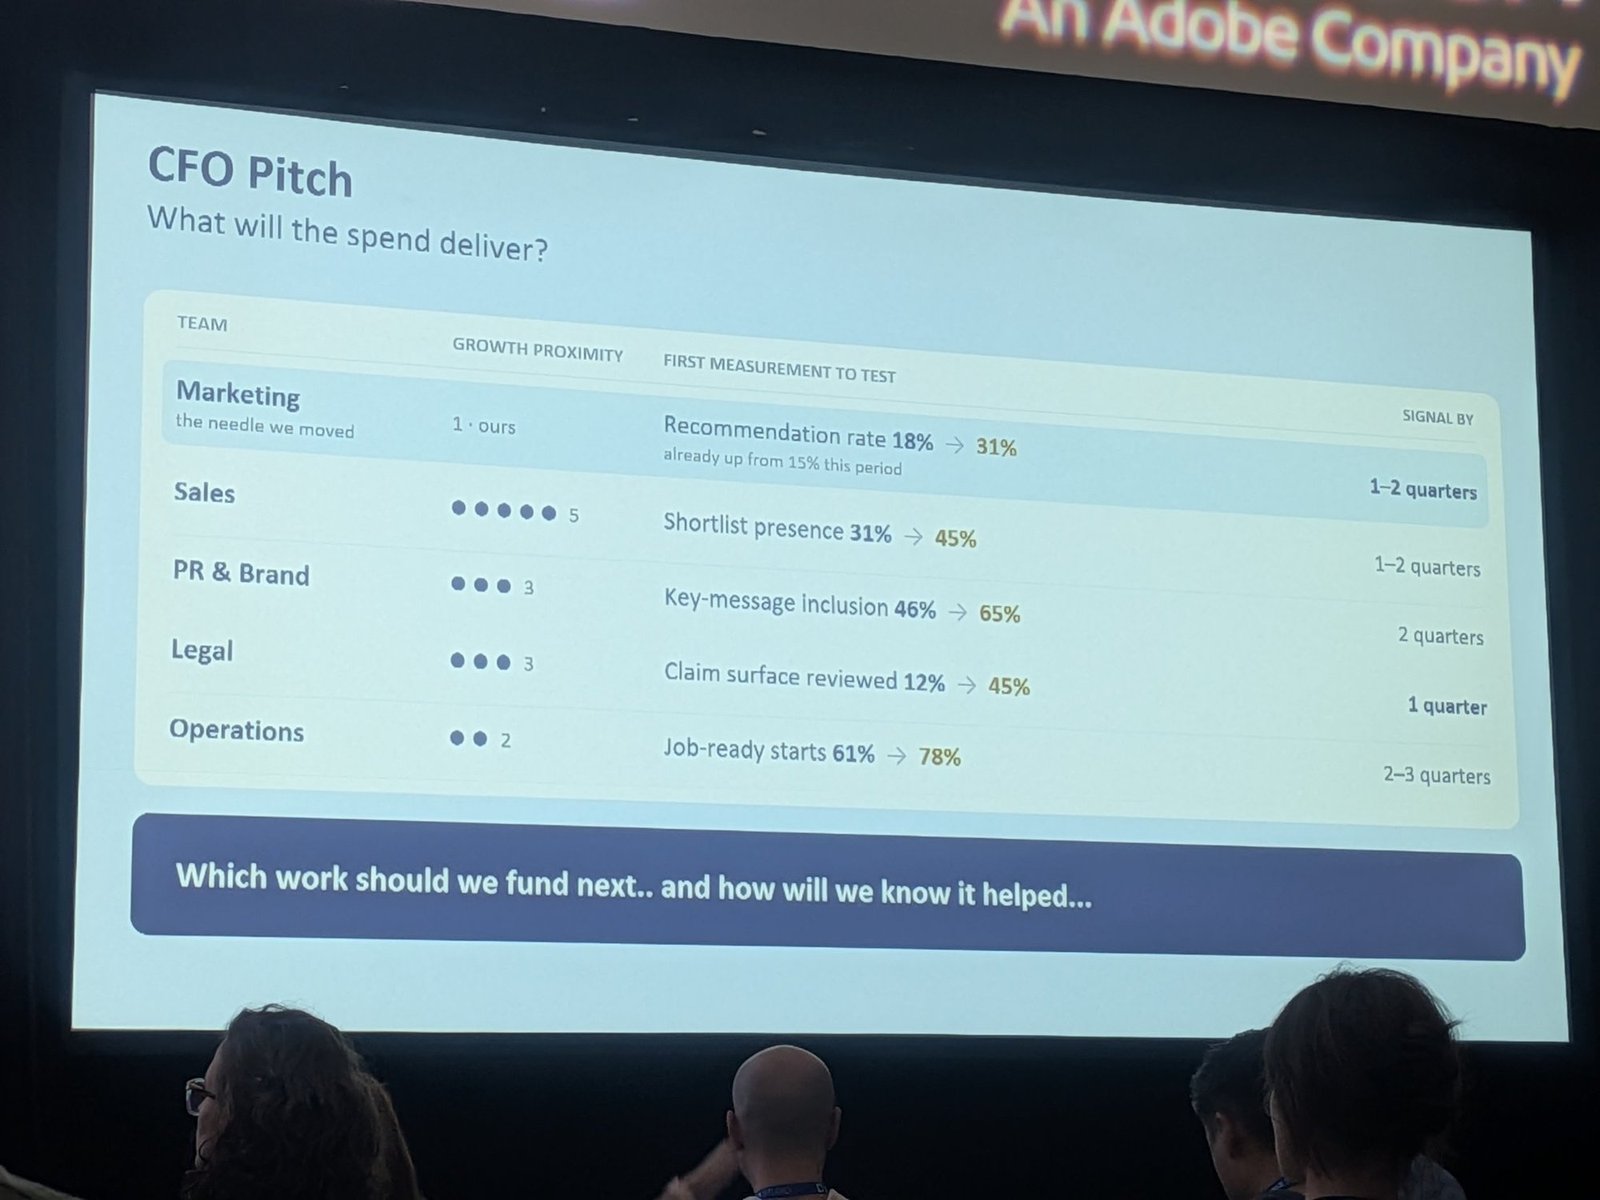
The CFO pitch brings the departments together by ranking them by proximity to growth, with a first measurement and a time frame for each:
| Team | Growth proximity | First measurement | Signal by |
|---|---|---|---|
| Marketing | Ours | Recommendation rate 18% to 31% (already up from 15% this period) | 1 to 2 quarters |
| Sales | 5 | Shortlist presence 31% to 45% | 1 to 2 quarters |
| PR & Brand | 3 | Key-message inclusion 46% to 65% | 2 quarters |
| Legal | 3 | Claim surface reviewed 12% to 45% | 1 quarter |
| Operations | 2 | Job-ready starts 61% to 78% | 2 to 3 quarters |
The framing question for the CFO: which work should we fund next, and how will we know it helped?
Designing Information for Customers
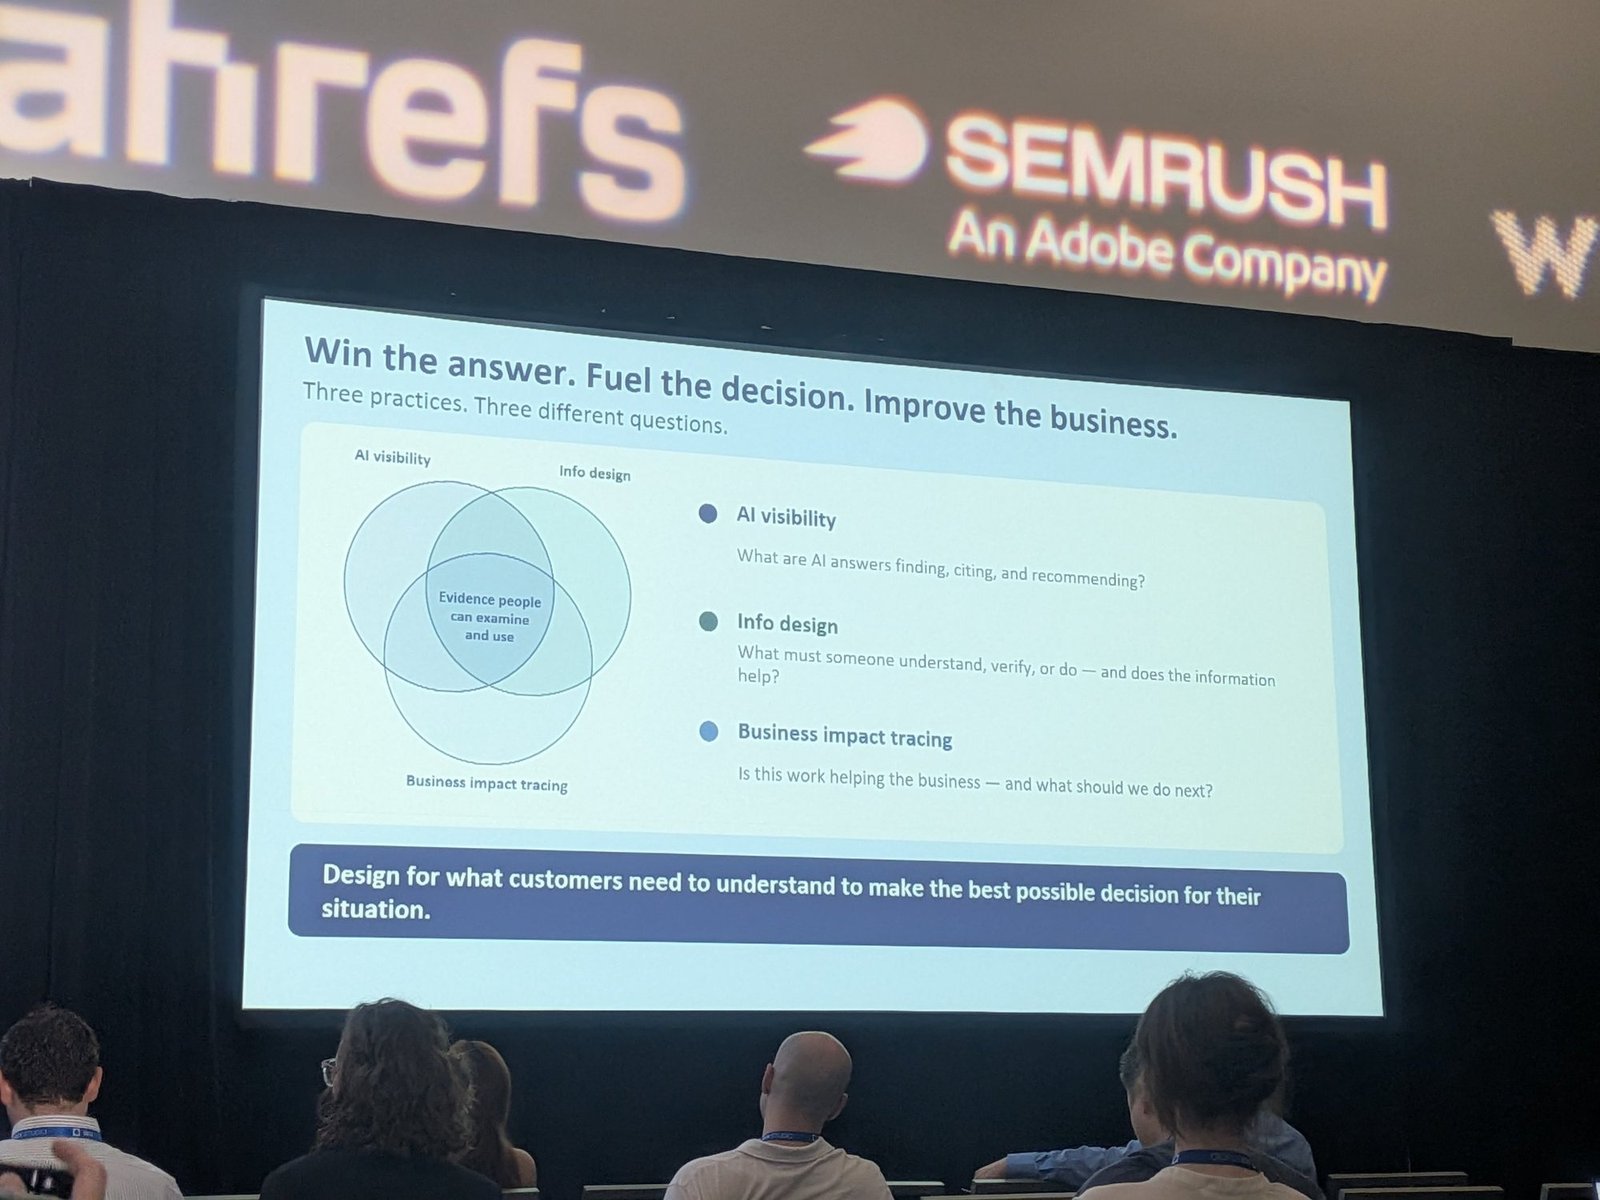
Garrett closed by connecting three practices, each answering a different question:
- AI visibility: what are AI answers finding, citing, and recommending?
- Information design: what must someone understand, verify, or do, and does the information help?
- Business impact tracing: is this work helping the business, and what should we do next?
Where all three overlap is evidence people can examine and use. The principle underneath: design for what customers need to understand to make the best possible decision for their situation. He was clear that this isn’t a visibility problem. It’s a customer problem, and a human one.
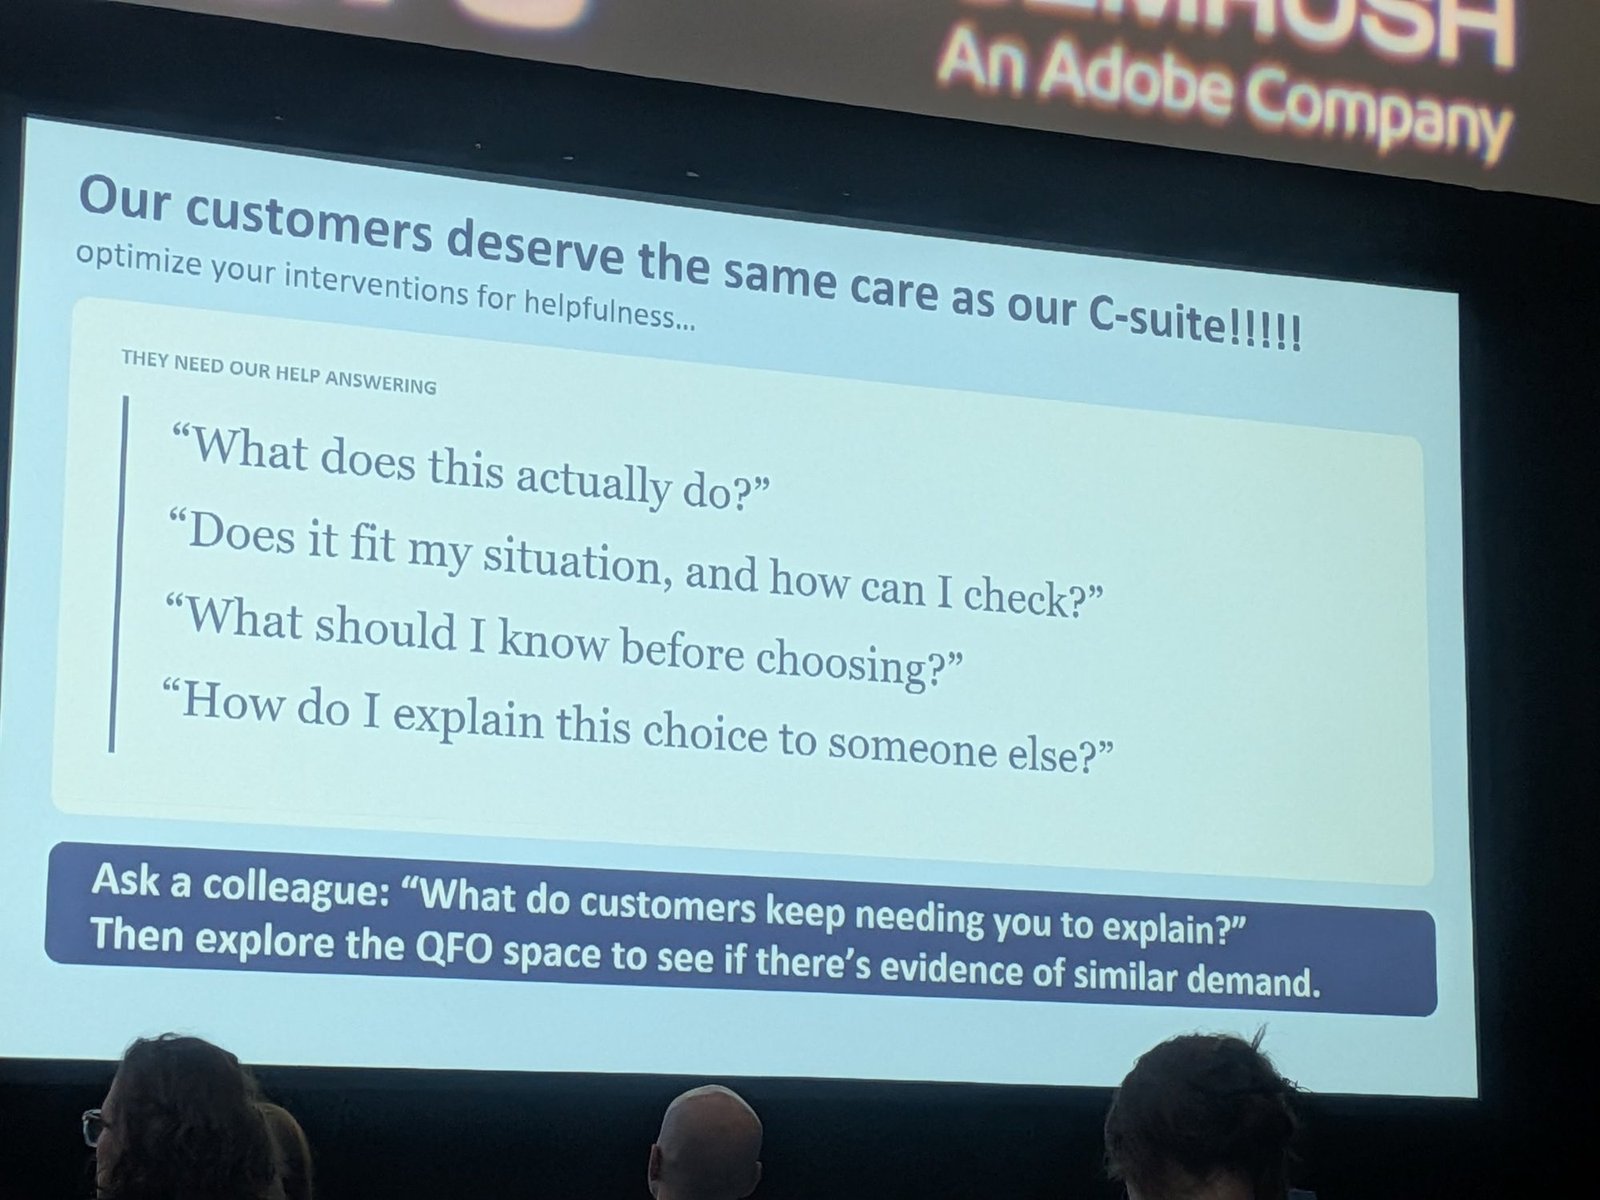
His final slide argued that customers deserve the same care we put into C-suite reporting. They need help answering four questions: what does this actually do, does it fit my situation and how can I check, what should I know before choosing, and how do I explain this choice to someone else?
The action on the slide: ask a colleague what customers keep needing them to explain, then look at the query fan-out space to see whether there is evidence of similar demand.
What Not to Do
- Don’t treat the diagnostic as a funnel. Getting cited doesn’t cause a recommendation. Use the flowchart to find where the gap is.
- Don’t stop at visibility or mentions. A mention without a recommendation, or a recommendation on the wrong terms, isn’t commercially useful.
- Don’t pitch traffic to departments that don’t care about traffic. Sales, legal, and finance each need their own outcome, in their own language.
- Don’t approach other departments without preparation. Garrett’s advice was to learn their problems and design the outcome you can offer before you walk into the meeting.
- Don’t overdo it. Building a dashboard for every team at once is not the goal. Start with the department where you can show impact.
Next Steps
- Write three decision prompts for your category. Base them on real buying decisions, not keywords, and leave your brand out.
- Run them repeatedly across several AI engines. Calculate your recommendation rate against your main competitors.
- Work through the six diagnostic checks. Identify the first step where you fail, and start your investigation there.
- Ask a colleague in sales or support what customers keep needing explained. Then look at query fan-outs to see whether AI is facing the same demand.
- List which surfaces you can actually change. If your website and publishers are blocked, look for a surface a decision-maker will approve.
- Pick one department and build its pitch. Define its outcome, a baseline, a target, and a realistic time frame.
Personal Takeaways
This was one of the most practical sessions I’ve seen on AI visibility, precisely because it didn’t stop at measurement. Many talks this year have introduced a framework for tracking AI mentions. Very few have addressed the obstacle that actually stops the work: other people in the organization saying no.
What I’m taking away:
- The “Getting approval” table is my new diagnostic for client readiness. Before recommending AI visibility work, I want to know which of these four surfaces a client can actually change. For Japanese companies entering the UK or US, the answer is often that the website sits with headquarters and legal review is slow. An offsite knowledge base may be the realistic first move.
- Recommendation rate is a better client KPI than mention counts. It connects directly to a buying decision, and it gives a benchmark against named competitors that is easy to explain.
- The legal pitch is underused. In regulated or claims-heavy industries, the point that nobody is monitoring what AI repeats about the company is a genuine risk, and it gives search teams a reason to be in the room.
- Sales objections are a content brief. This is simple, but it reframes where content ideas should come from in B2B.
Paired with Skyler Rudolfsky’s session just before, the morning built a clear argument. Skyler showed that AI influences decisions in ways clicks can’t reveal. Garrett showed how to measure that influence at the decision level and how to turn it into something other departments will fund.
Related Resources
- Session: AI & Search Behavior, brightonSEO San Diego 2026
- Speaker: Garrett French
- Citation Labs
- Skyler Rudolfsky’s session report: the previous session in the same block, on AI and search in the consumer journey
Written by Ayaka Uchida
CEO, A-Digital Works
This report covers Garrett French’s session “Win Decisions, Not Keywords: Mapping Buyer Choice Points for AI Visibility” at brightonSEO San Diego, September 16, 2026.
